ToolProven
Search tools and lists/All lists
We earn a commission if you buy through some links. It never changes a score or a rank.How we research →
The moat behind every score

How we research AI tools

Directories summarize. Rating sites crowdsource. AI blogs paraphrase. We read each maker’s own pages, date every fact and link it to where we read it — and a tool counts as tested only once its raw output from our published brief is on its page. Here’s exactly how, and how to check us.

We buy our own subscriptions
Where we have run the task, we ran it on a plan we paid for. No vendor gets a free pass, an easier brief or a comped account — and no tool is marked tested until its raw output is published.
No tool can buy a ranking
We don’t sell placements, featured spots or higher scores. Position is earned on the published facts, full stop.
Affiliate links never move scores
We earn commissions, and we disclose them — but the score is set before any link is added, and never changed for money.
The process

Six steps, every tool we cover

Bench coverage today

None of the 8 live tools has first-party output published yet. Every tool page carries a RESEARCH PROFILE banner: verified pricing, policy and feature research with dated primary sources, and provisional scores. We publish this number rather than let “tested” stand in for it.

01
Pick a real scenario
We start from a specific job — “faceless YouTube”, “UGC ads” — not a generic “best tool” list. It mirrors how people actually search.
02
Read the maker’s own pages
Pricing, plan limits, free-tier terms, licence and refund policy come from each maker’s own pricing page, help center and terms — quoted where the wording matters.
03
Date and link every fact
Each fact carries the date we read it and a link to where we read it, so you can check it yourself. A figure only a third party reports is labelled as such.
04
Score on four axes
Quality, speed, ease and value — never a single vague star. Value is weighted hardest. Until a tool is benched, its scores are provisional editor estimates and say so.
05
Add the human layer
A plain-English verdict, who it suits, and what we’d pick. This is the part an AI-spun blog can’t fake.
06
Re-read on every change
AI tools change pricing and plan limits almost weekly. We re-read the maker’s pages, update the page and its date, and log the change in the changelog.
The scorecard

Four axes, not one star

Borrowed from the best of the rating sites — the real buying signal lives in the sub-scores, especially value.

Quality30%
How good is the actual output, judged on the real export — not the marketing reel.
Speed15%
Time from brief to a usable result, including queue and render time.
Ease20%
Setup, learning curve and day-to-day friction for a non-expert.
Value35%
Output quality per dollar. Weighted hardest because it’s where hype dies.

A measured bench composite is the weighted sum above: Value 35% + Quality 30% + Ease 20% + Speed 15%, identical for every tool in a category. Scores labeled “provisional” on a page are editor estimates from pricing, policy and feature research — they are not produced by this formula, and one is replaced by the weighted composite only once that tool has been run through the brief below.

The standard briefs

The bench brief, published in full

No review site shows you what it actually fed the tools — which makes “we tested it” unfalsifiable. This is the brief a tool gets when we run it hands-on, published in full so every bench result is reproducible: paste the same brief into the same tool and check it. The coverage count above says how many tools have been through it. The brief embeds deliberate traps that separate good tools from great ones.

The 60-second faceless explainer brief

A finance-explainer script rendered 9:16 with default settings plus one round of obvious fixes. It exposes caption accuracy, scene-matching judgment (does the b-roll match the sentence?), avatar lip-sync on numerals, and render-queue honesty.

Scene 1 (hook, 0–8s): "If you got a 10% raise tomorrow, you'd be broke again by March. Here's why."

Scene 2 (concept, 8–25s): "It's called lifestyle creep. Every time your income rises, your spending quietly rises to meet it — the streaming upgrade, the nicer gym, the third delivery app. None of it feels like a decision."

Scene 3 (mechanism, 25–42s): "The fix isn't a budget. It's automation: the day a raise lands, route half of the increase to an account you never see. You can't spend what never arrives."

Scene 4 (proof, 42–52s): "People who automate savings save roughly three times more than people who rely on willpower — same income, same city, same rent."

Scene 5 (CTA, 52–60s): "Follow for one money mechanism a day — no hustle, no hype."

What this brief is designed to expose
  • Percentage + month name + invented compound ("lifestyle creep") for caption accuracy
  • Abstract concepts (automation, willpower) — stock-footage engines must find non-literal b-roll
  • Tight per-scene timing — tests whether the tool respects pacing or pads scenes
  • A statistics sentence — tests on-screen text/number rendering
Receipts

What we can show you

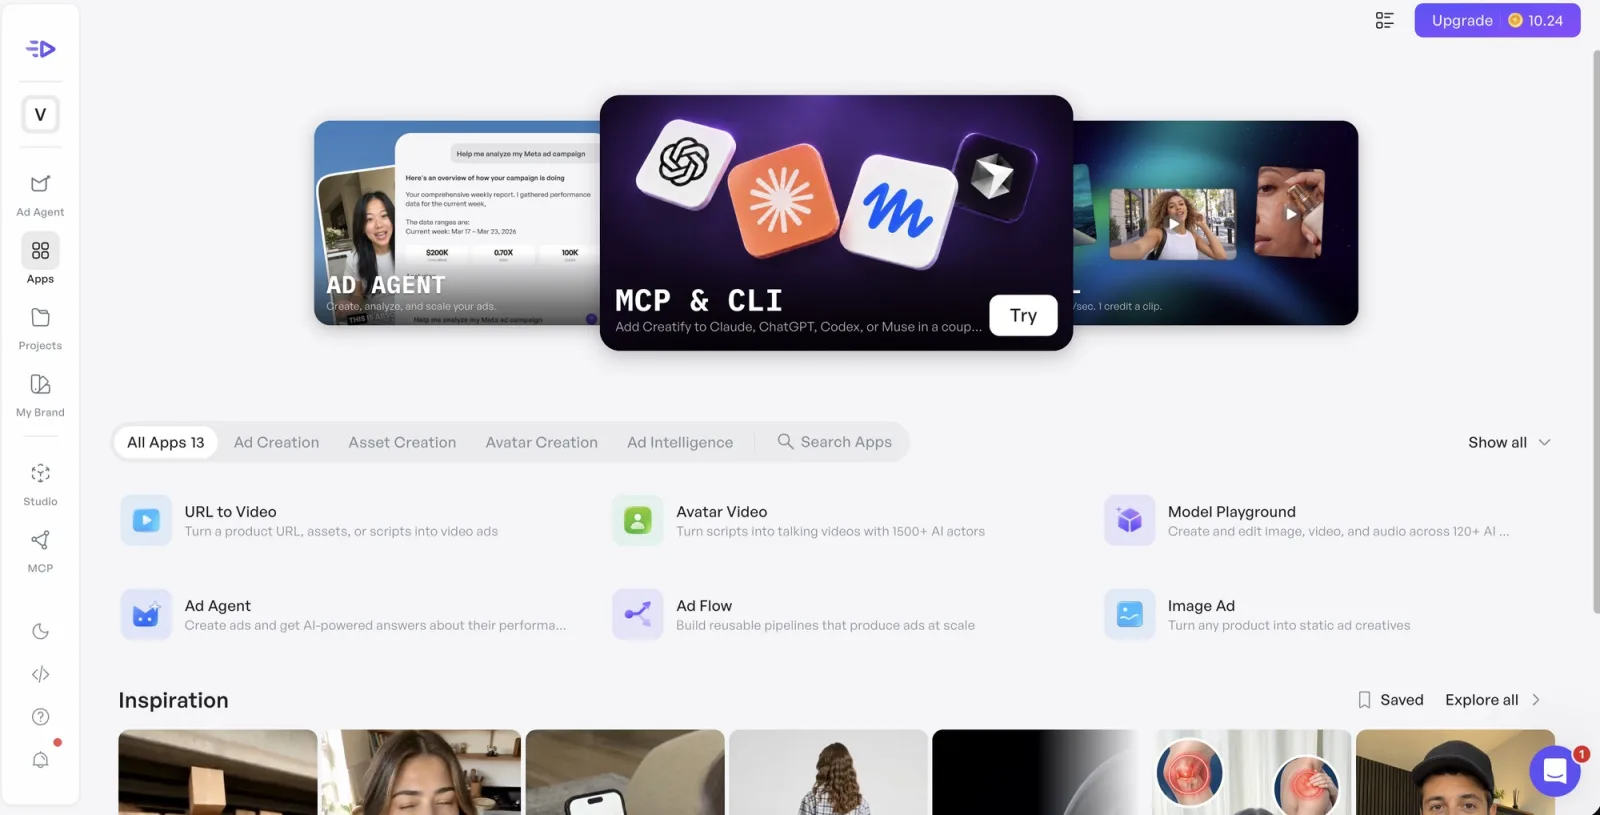
Our own Creatify accountScreenshot
Creatify Apps hub: banners for Ad Agent and MCP & CLI, and an All Apps 13 list showing URL to Video, Avatar Video with 1500+ AI actors, Model Playground with 120+ AI models, Ad Agent, Ad Flow and Image Ad.
Captured Oct 4, 2026 on our own Creatify account. It shows the app, not a test run — the Creatify review carries the rest.
Freshness policy
Every page carries the date its facts were read. If a tool ships a major update or changes pricing, we re-read its pages, update the page and the date, and log the change in the changelog. Stale reviews lose trust — and rankings.
V
Vincent Ruan
Founder & editor. Tools that have been through the bench were run hands-on, on a plan we paid for; the best-of lists compare what makers publish, and say so on every page.
See the method in action
Browse a scenario ranking built this way, every pick dated and sourced.
View the faceless YouTube ranking →